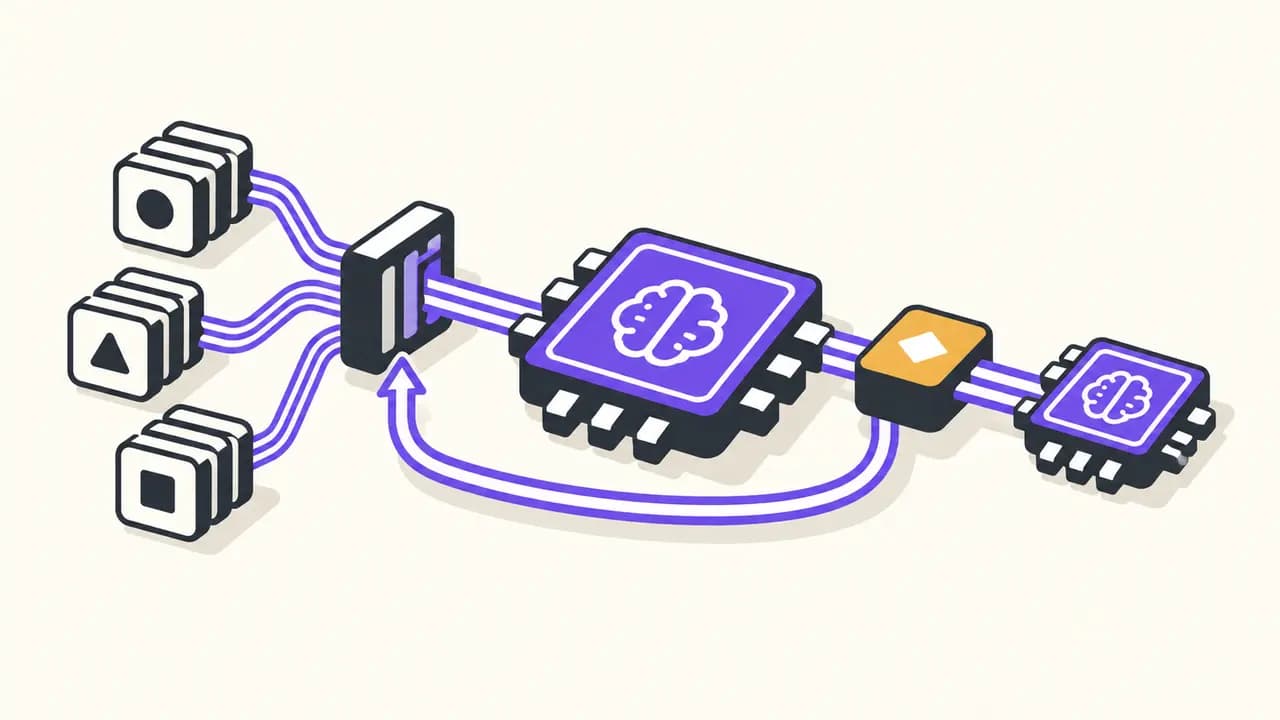
IBM describes an LLM guardrail that learns from real production data. Published on September 10, 2026, US application US20260268157A1 combines clustering, targeted annotation and repeated fine-tuning. A benchmark then determines whether to distil a compact update.
From a small seed set to a continuous feedback loop
The method first trains a classifier on a labelled seed dataset. IBM uses a filter that recognises health advice in LLM inputs or outputs as an example. The classifier then searches unlabelled production data for positive matches and groups their embeddings into clusters.
Instead of reviewing every match, the system can annotate a cluster centroid or one randomly selected sample and propagate that label to the other points. The classifier is fine-tuned on these labels, checkpointed and tested again against a curated dataset. Claims 1–7 cover this loop of selection, clustering, annotation, fine-tuning and benchmark comparison.
If measured performance falls below a threshold, the application adds another step: equal-sized samples are drawn from current and earlier production data. The current and previous model checkpoints generate soft class probabilities for them. A smaller model is meant to absorb both knowledge states and replace the current checkpoint. The description gives statistically significant degradation as an example, but defines no fixed production threshold.
Pandorex assessment: Less manual work, a new error path
The practical appeal is scale. Teams could expand a narrow, domain-specific guardrail with real usage patterns without manually labelling every production example. Reusing an earlier checkpoint is also intended to keep a new data wave from displacing cases the model had already learned.
The clustering shortcut remains risky. A wrong label on the selected point can propagate across an entire cluster, while rare cases or examples missed by the initial classifier may never enter the learning loop. The reviewed filing provides no comparative benchmark establishing accuracy, false-positive rates, compute cost or privacy effects in a production product.
Document status, checked September 13: a published US patent application by International Business Machines Corporation, filed March 7, 2025, as 19/073,433. It names Anna Lisa Gentile, Kellen Cheng and Chad Eric DeLuca. The A1 publication is neither a patent grant nor evidence that IBM deploys the method in a product.