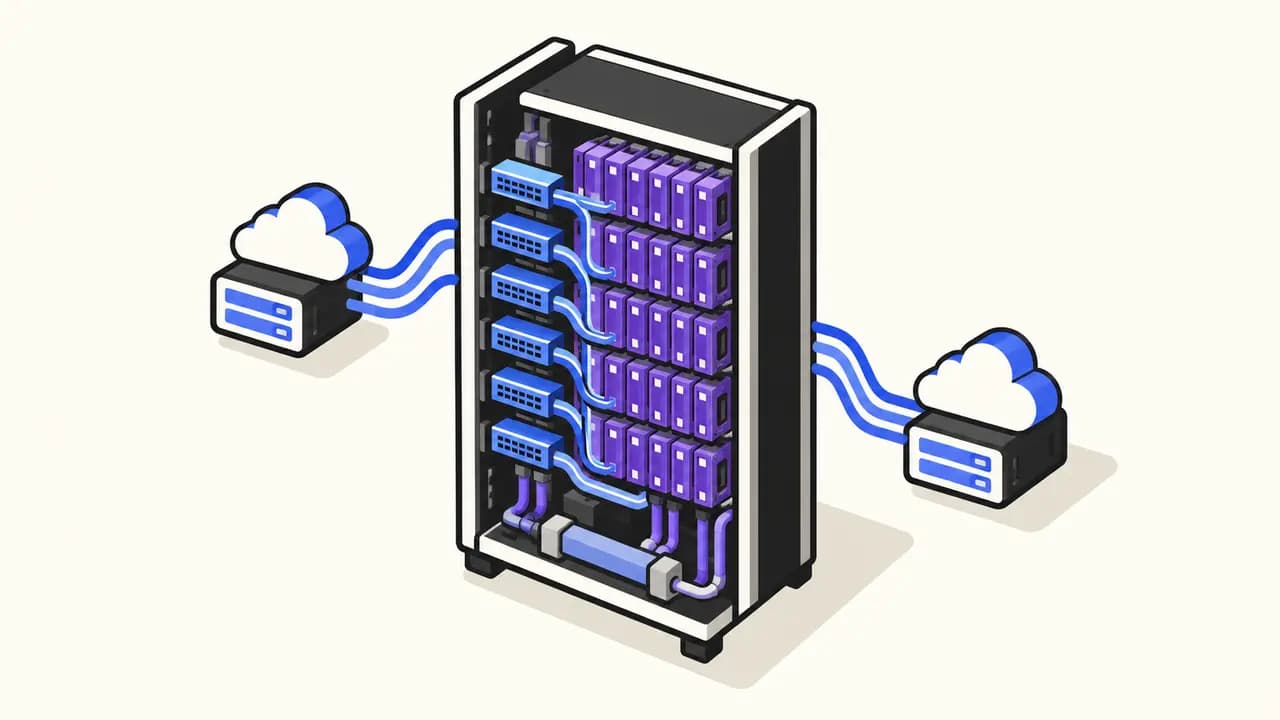
In brief: Vultr has placed a $1.2 billion order for HPE’s first AMD Helios racks for US data centres. Each rack links 72 Instinct MI455X GPUs through six Ethernet switch trays. The deal is a significant commercial test for open scale-up networking, but neither the rack count nor the delivery schedule is disclosed.
What is inside the rack
HPE integrates AMD Instinct MI455X accelerators, “Venice” EPYC processors, Pensando Vulcano AI NICs and ROCm. Six HPE Juniper QFX5252 switch trays connect all 72 GPUs inside one rack. HPE says the design supports open scale-up fabrics such as UALink over Ethernet, while direct liquid cooling removes heat. Vultr plans to deploy the systems in its US cloud data centres.
HPE is therefore selling more than servers and accelerators: it is supplying a coordinated rack stack spanning compute, networking, software and cooling. Juniper technology sits in the fastest communication path. Scale-up networking links GPUs within the system, while a separate scale-out network connects racks or clusters. That distinction matters because training and large inference workloads are sensitive to bandwidth, latency and collective communication.
An order is not a deployment
The $1.2 billion figure is an order value, not recognised revenue or deployed capacity. HPE and Vultr disclose neither the number of racks, delivery timing, contract mix nor unit prices. The total therefore cannot support credible cost-per-GPU or cost-per-rack calculations. No independent performance or efficiency measurements of the completed Vultr system are available either.
Separately, HPE forecasts a low-to-high-50s compound annual growth rate for data-centre networking revenue from fiscal 2026 through fiscal 2029. Its investor presentation names scale-up Ethernet and liquid cooling as growth drivers. HPE has also doubled networking supply purchase commitments and expects constraints to ease only into fiscal 2027. These are company forecasts, not realised results.
Pandorex Analysis
The order makes HPE’s Juniper acquisition commercially visible inside a large AMD scale-up rack for the first time. It supports the view that cloud providers want to test Ethernet- and UALink-based architectures alongside proprietary GPU interconnects. It does not prove lower total cost, equivalent latency or equal software maturity. “Open” describes the interface strategy; the delivered stack remains tightly integrated across HPE, AMD, Juniper and ROCm. Actual shipment volumes and independent cluster measurements will be the decisive evidence.